Z-sight: Unifying Vision-Language-Action and Latent World Modeling
Oct 1, 2026· ,,,,,,,,,,,,,(* Equal Contribution, † Equal Advising)
·
1 min read
Junjie Ye*
Yiqi Zhao*
Muchen Xu*
Celina Shiyu Wang
Hao Dong
Ruohai Ge
Rong Xue
Benjamin J. Kolligs
Aditya Dutt
Sasanka Nagavalli
Nassim A. Samad
Gaurav S. Sukhatme
Jyotirmoy V. Deshmukh
Yue Wang†
Yuliang Guo†
Abstract
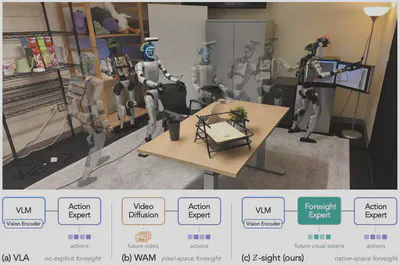
We introduce Z-sight, a unified robot foundation model that brings vision-language-action modeling and world modeling together through feature-space future prediction. Whereas video-based world action models (WAMs) adapt pretrained video generators at substantial computational cost, Z-sight predicts the future in the native visual representation space of a pretrained vision-language model (VLM), so the policy perceives the present and predicts the future within a shared visual foundation. A foresight expert and a continuous action expert are coupled to the VLM through a mixture-of-transformers: the foresight expert denoises future spatial visual tokens, while the action expert attends to this prediction stream to generate actions, enabling joint learning from robot trajectories and human egocentric video without pixel reconstruction. On a real humanoid robot, Z-sight achieves a 62% average success rate across five manipulation tasks, outperforming VLA and WAM baselines by a large margin, while running at 110 ms per action chunk.
Type
Publication
Under Review